We already had the opportunity to talk about Replication between MySQL Database in a previous article, where we described it as a great way to increase the security and reliability of data storage without spending a fortune. In this article we will see what to do when the Replication stops working: how to notice, what can I do to restore it and, most importantly, how to ensure that the data is re-synchronized.
Identify causes
The first thing to do is make sure that the Replication is actually broken. Although in most cases we can clearly see it by just looking at the replicated data, we need to check it in an objective way. In order to do this go to the Slave, issue the command SHOWSLAVE STATUS – or SHOWSLAVE STATUS\G if you prefer to read the results in human-readable format – and go read the column contents: Slave_SQL_Running and Slave_IO_Running: if there’s at least a NO, that means that the Replication is actually broken, otherwise the problem is attributable to other causes. Lire la suite…
One means of restricting client use of MySQL server resources is to set the global max_user_connections system variable to a nonzero value. This limits the number of simultaneous connections that can be made by any given account, but places no limits on what a client can do once connected. In addition, settingmax_user_connections does not enable management of individual accounts. Both types of control are of interest to MySQL administrators.
To address such concerns, MySQL permits limits for individual accounts on use of these server resources:
The number of queries an account can issue per hour
The number of updates an account can issue per hour
The number of times an account can connect to the server per hour
The number of simultaneous connections to the server by an account
Any statement that a client can issue counts against the query limit, unless its results are served from the query cache. Only statements that modify databases or tables count against the update limit.
An “account” in this context corresponds to a row in the mysql.user table. That is, a connection is assessed against the User and Host values in the user table row that applies to the connection. For example, an account 'usera'@'%.example.com' corresponds to a row in the user table that has User and Host values of usera and %.example.com, to permit usera to connect from any host in the example.com domain. In this case, the server applies resource limits in this row collectively to all connections by usera from any host in the example.com domain because all such connections use the same account.
Before MySQL 5.0.3, an “account” was assessed against the actual host from which a user connects. This older method of accounting may be selected by starting the server with the --old-style-user-limits option. In this case, if usera connects simultaneously from host1.example.com andhost2.example.com, the server applies the account resource limits separately to each connection. If usera connects again from host1.example.com, the server applies the limits for that connection together with the existing connection from that host.
To establish resource limits for an account at account-creation time, use the CREATE USER statement. To modify the limits for an existing account, use ALTER USER. (Before MySQL 5.7.6, use GRANT, for new or existing accounts.) Provide a WITH clause that names each resource to be limited. The default value for each limit is zero (no limit). For example, to create a new account that can access the customer database, but only in a limited fashion, issue these statements:
mysql> CREATE USER 'francis'@'localhost' IDENTIFIED BY 'frank'
    ->     WITH MAX_QUERIES_PER_HOUR 20
    ->          MAX_UPDATES_PER_HOUR 10
    ->          MAX_CONNECTIONS_PER_HOUR 5
    ->          MAX_USER_CONNECTIONS 2;
The limit types need not all be named in the WITH clause, but those named can be present in any order. The value for each per-hour limit should be an integer representing a count per hour. For MAX_USER_CONNECTIONS, the limit is an integer representing the maximum number of simultaneous connections by the account. If this limit is set to zero, the global max_user_connections system variable value determines the number of simultaneous connections. Ifmax_user_connections is also zero, there is no limit for the account.
Database replication is a technique where a given database is copied to one or more locations, so that the reliability, fault-tolerance or accessibility of the database can be improved. Replication can be snapshot-based (where entire data is simply copied over to another location), merge-based (where two or more databases are merged into one), or transaction-based (where data updates are periodically applied from master to slaves).
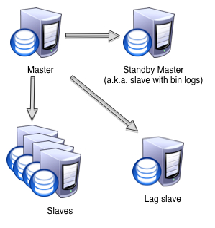
MySQL replication is considered as transactional replication. To implement MySQL replication, the master keeps a log of all database updates that have been performed. The slave(s) then connect to the master, read individual log entries, and perform recorded updates. Besides maintaining a transaction log, the master performs various housekeeping tasks, such as log rotation and access control. When new transactions occur and get logged on the master server, the slaves commit the same transactions on their copy of the master database, and update their position in the master server’s transaction log. This master-to-slave replication process is done asynchronously, which means that the master server doesn’t have to wait for the slaves to catch up. If the slaves are unable to connect to the master for a period of time, they will download and execute all pending transactions when connectivity is re-established.
Database replication allows one to have an exact copy of a live database of a master server at another remote server (slave server) without taking the master server offline. In case the master server is down or having any trouble, one can temporarily point database clients or DNS resolver to the slave server’s IP address, achieving transparent failover. It is must be noted that MySQL replication is not a backup solution. For example, if an unintended DELETE command gets executed in the master server by accident, the same transaction will mess up all slave servers.
In this article, we will demonstrate master-slave based MySQL replication on two Linux computers. Let’s assume that the IP addresses of master/slave servers are 192.168.2.1 and 192.168.2.2, respectively.
Setting up a Master MySQL Server
This part will explain the steps needed on the master server.
First, log in to MySQL, and create test_repl database.
$ mysql -u root -p
mysql> CREATE DATABASE test_repl;
Next, create a table inside test_repl database, and insert three sample records.
mysql> USE test_repl;
mysql> CREATE TABLE employee (EmployeeID int, LastName varchar(255), FirstName varchar(255), Address varchar(255), City varchar(255));
mysql> INSERT INTO employee VALUES(1,"LastName1","FirstName1","Address1","City1"),(2,"Lastname2","FirstName2","Address2","City2"),(3,"LastName3","FirstName3","Address3","City4");
After exiting the MySQL server, edit my.cnf file using your favorite text editor. my.cnf is found under /etc, or /etc/mysql directory.
The server-id option assigns an integer ID (ranging from 1 to 2^23) to the master server. For simplicity, ID 1 and 2 are assigned to the master server and the slave server, respectively. The master server must enable binary logging (with log-bin option), which will activate the replication. Set the binlog-do-db option to the name of a database which will be replicated to the slave server. The innodb_flush_log_at_trx_commit=1 and sync_binlog=1options must be enabled for the best possible durability and consistency in replication.
After saving the changes in my.cnf, restart mysqld daemon.
# systemctl restart mysqld
or:
# /etc/init.d/mysql restart
Log in to the master MySQL server, and create a new user for a slave server. Then grant replication privileges to the new user.
mysql> CREATE USER [email protected];
mysql> GRANT REPLICATION SLAVE ON *.* TO [email protected] IDENTIFY BY 'repl_user_password';
mysql> FLUSH PRIVILEGES;
A new user for the slave server is repl_user, and its password is repl_user_password. Note that the master MySQL server must not bind to the loopback interface since a remote slave server needs to log in to the master server as repl_user. Check this tutorial to change MySQL server’s binding interface.
Finally, check the master server status by executing the following command on the server.
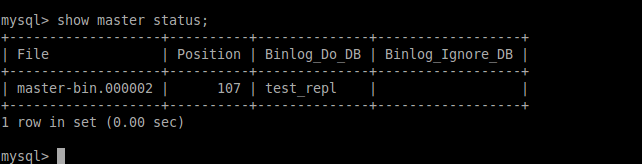
mysql> SHOW MASTER STATUS;
Please note that the first and second columns (e.g., master-bin.000002 and 107) will be used by the slave server to perform master-to-slave replication.
Ce qui permet de réinjecter des données résultantes d’un SELECT * FROM base.table WHERE my_id='66666666'.
Il est évidement possible de faire toutes ces opération sur une instance en précisant son port avec l’option –port (valable pour mysqldump et mysql).
Pour obtenir une liste des utilisateurs mysql, on peut utiliser cette fonction (glanée sur serverfault) :
mygrants()
{
  mysql -B -N -e "SELECT DISTINCT CONCAT(
    'SHOW GRANTS FOR ''', user, '''@''', host, ''';'
    ) AS query FROM mysql.user" |
  mysql |
  sed 's/(GRANT .*)/1;/;s/^(Grants for .*)/## 1 ##/;/##/{x;p;x;}'
}
On peut choisir 3 types de format pour les binlogs :
statement : les requêtes INSERT / UPDATE sont conservées
row : les modifications de chaque ligne sont conservées (via une sorte de code « binaire » propre à MySQL)
mixed : en mode statement… sauf dans certains cas où cela passe en mode row
Avantages et inconvénients :
Le mode statement est utile pour conserver en clair toutes les requêtes. Il permet aussi de meilleures performances quand des UPDATE contiennent des clauses WHERE qui modifient de nombreuses lignes. Pour de la réplication, il peut être non fiable car le résultat d’un UPDATE peut donner des résultats différents sur un serveur SLAVE. Cela peut aussi poser des soucis avec les transactions InnoDB.
Le mode row a l’inconvénient de rendre illisibles toutes les requêtes. Dans certains cas particuliers (UPDATE contiennent des clauses WHERE qui modifient de nombreuses lignes), il peut être moins performant. Il a l’avantage d’être plus fiable pour de la réplication.
Le mode mixed est un bon compromis pour de la réplication : il permet de voir la plupart des requêtes en clair, mais évite le problème de fiabilité en passant en mode row quand c’est nécessaire.
Suppression
Pour supprimer les binlogs antérieurs à mysql-bin.00NNNN :
mysql> PURGE BINARY LOGS TO 'mysql-bin.00NNNN';
ou par rapport à une date :
mysql> PURGE BINARY LOGS BEFORE "2011-12-07 00:00:00";
Désactivation
Pour désactiver les binlogs, on ajoutera l’option suivante dans la configuration :
disable-log-bin
Lecture
On pourra lire en ligne de commande le contenu d’un binlog via la commande :
# mysqlbinlog /var/log/mysql/mysql-bin.001789 | less
Note : si vous obtenez une erreur mysqlbinlog: unknown variable 'default-character-set=utf8' c’est que la directive default-character-set a été placée dans la configuration MySQL (/etc/mysql ou .my.cnf) dans la mauvaise section : [client] au lieu de [mysql] (ou [mysqldump]).
Replay
ATTENTION, CES MANIPULATIONS PEUVENT ÊTRE DANGEREUSES POUR VOS DONNÉES, BIEN SAVOIR CE QUE L’ON FAIT.
On pourra ainsi injecter le contenu d’un binlog dans une base… tout simplement avec une commande du type :
# mysqlbinlog /var/log/mysql/mysql-bin.001789 | mysql -P3307
À noter que si une partie des données étaient déjà présentes (cas d’un binlog corrompu lors d’incident lors d’une réplication), on pourra procéder ainsi :
# mysqlbinlog /var/log/mysql/mysql-bin.001789 > mysql-bin.001789.txt
# sed -i 's/INSERT INTO/INSERT IGNORE INTO/gi' mysql-bin.001789.txt
# cat mysql-bin.001789.txt | mysql -P3307
Log des requêtes lentes
Pour débugger les applications lentes, c’est une fonctionnalité intéressante de trouver quel requête est longue. Pour cela on peut spécifier quand une requêtes est considéré comme longue, le chemin où stocker les requêtes, et l’activation des logs.