Archive

Articles taggués ‘monitoring’

Bandwidth monitoring with iptables

22/05/2024 Comments off

Source: By Gerard Beekmans

Linux has a number of useful bandwidth monitoring and management programs. A quick search on Freshmeat.net for bandwidth returns a number of applications. However, if all you need is a basic overview of your total bandwidth usage, iptables is all you really need — and it’s already installed if you’re using a Linux distribution based on the 2.4.x or 2.6.x kernels.

Most of the time we use iptables to set up a firewall on a machine, but iptables also provides packet and byte counters. Every time an iptables rule is matched by incoming or outgoing data streams, the software tracks the number of packets and the amount of data that passes through the rules.

It is easy to make use of this feature and create a number of « pass-through rules » in the firewall. These rules do not block or reroute any data, but rather keep track of the amount of data passing through the machine. By using this feature, we can build a simple, effective bandwidth monitoring system that does not require additional software.

Depending on how the firewall rules are set up, the setup for bandwidth monitoring may be very simple or very complex. For a desktop computer, you may need to create only two rules to log the total input and output. A system acting as a router could be set up with additional rules to show the totals for one or more subnets, right down to the individual IP address within each subnet. In addition to knowing exactly how much bandwidth each host and subnet on the network is using, this system could be used for billing or chargeback purposes as well.

Rules setup

The rules setup itself is quick and straightforward, and takes only a few minutes. Obviously, you need to be root or use sudo to insert iptables rules.

The examples in this article are based on a router that provides Internet service to various towns. The iptables rules keep track of how much bandwidth each town uses and how much bandwidth each customer in that town uses. At the end of each month, an administrator checks the counters. Individuals who use more than they were supposed to get billed for over usage, the counters are reset to zero, and the process is repeated at the beginning of the next month.

The IP addresses in this article are modified from the real addresses. We’ll use the private IP space 192.168.0.0/16, subnetted into smaller blocks.

First, we will create two custom chains for the two towns and put town-specific rules in them. This will keep the built-in FORWARD chain relatively clean and easy to read. In this example, the FORWARD chain will only provide the global counters (all customers combined on a per-town basis).

iptables -N town-a
 iptables -N town-b

The next data element is the total bandwidth counter. Because this machine is a router only, the INPUT and OUTPUT chains are of little interest. This machine will not be generating a significant amount of bandwidth (i.e., it is not serving as a mail or Web server), nor will it be receiving significant uploads from other hosts.

Total bandwidth downloaded by and uploaded to the two towns combined:

iptables -A FORWARD

This is the easiest of rules. The rule will match any source and any destination. Everything that is being passed through this router matches this rule and will provide the total of combined downloaded and uploaded data.
Lire la suite…

iptables recent matching rule

21/05/2024 Comments off

Source: zioup.org

Linux iptables now offers extended packet matching modules. The recent module tracks IP addresses and allows to match against them using other criteria.

We are going to use a combination of lists created by the recent module and a new chain to track attackers. The two problems we are trying to minimise are:

  • centralised port scans.
  • ssh attacks: somebody tries to log in through ssh from a unique ip address using different user IDs and passwords.

port scan

A port scan will try to talk to our machine on different ports. The idea here is to ban the offending ip address as soon as it touches a non-authorised port.

We accomplish this by creating two rules. The first one has to be the last rule in the INPUT chain, it replaces your rule that says that if a packet has not matched any rule it should be DROPped. Additionally to DROPping the packet, we add the source ip address to the « badguys » list:

iptables ...
 .
 .
 .
iptables -A INPUT  -t filter -i $OUTS -j DROP -m recent --set --name badguys

The next rule will be the first rule of the INPUT chain and will block any packet from ip addresses that are present in the badguys list and for which we have received packet within the last hour. Note that we use the « –update » option rather than « –rcheck », so that any new packet resets the clock ; offenders have to be completely silent for one hour in order to be able to communicate with us again:

iptables -A INPUT -i $OUTS -m recent --name badguys --update --seconds 3600 -j DROP
iptables ...
 .
 .
 .
iptables -A INPUT  -t filter -i $OUTS -j DROP -m recent --set --name badguys

Lire la suite…

Use iptables to monitor network usage

20/05/2024 Comments off

Iptables is a powerful firewall/packet filtering framework inside Linux, and obviously used for firewalls on desktop, servers, and even embedded Linux devices such as most home internet routers. I was asked to write a script that could monitor and report network usage on one of our machines at work.

I took on the challenge and after searching package repositories and Google for cool Linux console apps that will report network usage, I came came across the idea of using iptables.. seeing as I love iptables, and it is installed by default on most machines it was the perfect solution for us.

The Idea
Iptables can be thought of a bunch of tables each containing some lists of rules called “chains”. There are some default chains which packets must progress through depending on the packets origin and destination. The main and default table that most people use is the ‘filter’ table, the default chains are:

  • INPUT – Packets coming to the machine from the network.
  • OUTPUT – Packets leaving your machine,
  • FORWARD – Packets passing through your machine, if your machine routes packets.

Each of these chains have a default policy, that is what should happen if there is no rules or no rules matching the packet, this is either:

  • ACCEPT – Allow the packet into the machine.
  • DROP – Drop the packet,

Now the default chains cannot be changed, the packets will work through one of those chains, we can add any rules we want to filter these packets. Netfilter/iptables tracks the amount of data running through chains. So if you want to track all your incoming network usage you can just use the INPUT chain, but if we want to track more specific traffic, we can create a custom chain, add a rule to pass the specific packets to this new chain, and thus monitor the specific traffic! Easy huh!

Before I go into the script and specific iptables configuration I’ll show you readers some useful itptables commands:

  • To see the manual page on iptables: man iptables
  • To list the rules on the default (filter) table: iptables -L
  • To list rules on other tables: iptables -t <tablename> -L

NOTE: If you add a -v you can see packet and byte counts.

Now we move onto what I did.

Lire la suite…

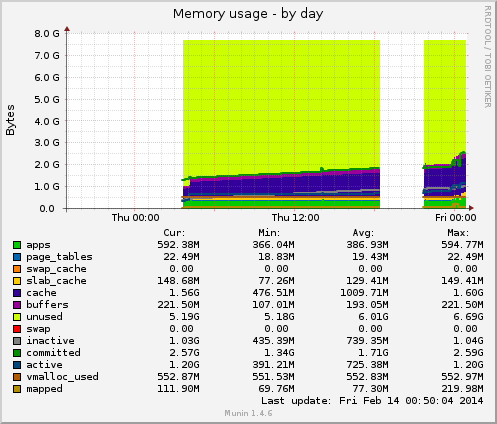
How do I change, sort, add, remove graphs with Munin?

17/05/2024 Comments off

Graphs on Munin

Enable and disable plugins on each node

graphs muninGraphs are added and removed via symlinks in the /etc/munin/plugins/ directory of the node.
To remove a graph you must remove the symlink and restart the node:

rm /etc/munin/plugins/diskstats
service munin-node restart

To add a graph you must add a symlink in the plugins directory to an executable. eg:

ln -s /usr/share/munin/plugins/diskstats /etc/munin/plugins/diskstats
service munin-node restart

When you restart munin-node it runs immediately and any issues with the plugins appears in /var/log/munin/munin-node.log. If all is going well you’ll see a CONNECT logged every cycle; this records the fact that the master connected to collect the latest data.

Process Backgrounded
2014/03/10-15:59:47 Munin::Node::Server (type Net::Server::Fork) starting! pid(32231)
Resolved [*]:4949 to [::]:4949, IPv6
Not including resolved host [0.0.0.0] IPv4 because it will be handled by [::] IPv6
Binding to TCP port 4949 on host :: with IPv6
2014/03/10-16:00:04 CONNECT TCP Peer: "[::ffff:203.28.51.227]:45965" Local: "[::ffff:50.23.111.122]:4949"
2014/03/10-16:05:04 CONNECT TCP Peer: "[::ffff:203.28.51.227]:46109" Local: "[::ffff:50.23.111.122]:4949"
2014/03/10-16:10:04 CONNECT TCP Peer: "[::ffff:203.28.51.227]:46109" Local: "[::ffff:50.23.111.122]:4949"

Lire la suite…

How To Optimize WordPress Performance With MySQL Replication On Ubuntu 14.04

10/05/2024 Comments off

Introduction

In this tutorial, we will teach you how to scale up your WordPress MySQL database server setup using master-slave database replication and the HyperDB plugin for WordPress. Adding more database servers to your environment in this manner allows your WordPress application to read from multiple database servers, increasing read performance.

MySQL replication reaps the most performance benefits for a system that processes frequent reads and infrequent writes, like most WordPress installations. By using a single-master with multiple-slave setup, you can add more slaves to scale your system, until you run out of network bandwidth or your master cannot handle the update load. If you wish, you can add more than one slaves by repeating the « slave » portions of the replication sections of this tutorial.

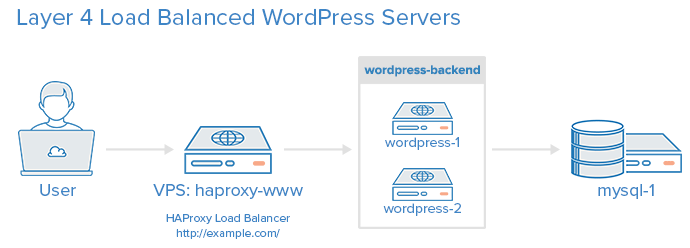
We are assuming that your setup includes two load balanced WordPress application servers that connect to a separate MySQL database server (see the prerequisites for a tutorial on how to set that up). It is not strictly necessary to have load balanced application servers to follow this tutorial, but your MySQL database server should be separate from your application servers.

Prerequisites

Before continuing with this tutorial, you should have completed two tutorials or have a similar environment:

After following those tutorials, to set up WordPress with two load balanced web application servers and a separate database server, you should have four VPSs. Because we will be dealing with several VPSs, for reference purposes, we will call your four existing VPSs the following:

  • haproxy-www: Your HAProxy server for layer 4 load balancing your WordPress web application servers. This is the entry point into your website
  • wordpress-1: Your first WordPress web application server
  • wordpress-2: Your second WordPress web application server
  • mysql-1: Your MySQL server for WordPress

That is, your environment should look something like this:

WordPress and Separate MySQL Database Server

In addition to your current environment, we will require one additional VPS during this tutorial. We will call it:

  • mysql-2: Your slave MySQL database server

Lire la suite…